效果示例
Doc2X 网页版现有的双语对照效果:以解析出的段落为单位,左边原文、右边译文,公式与表格保持原样。双语对照翻译 API 正在开发中。
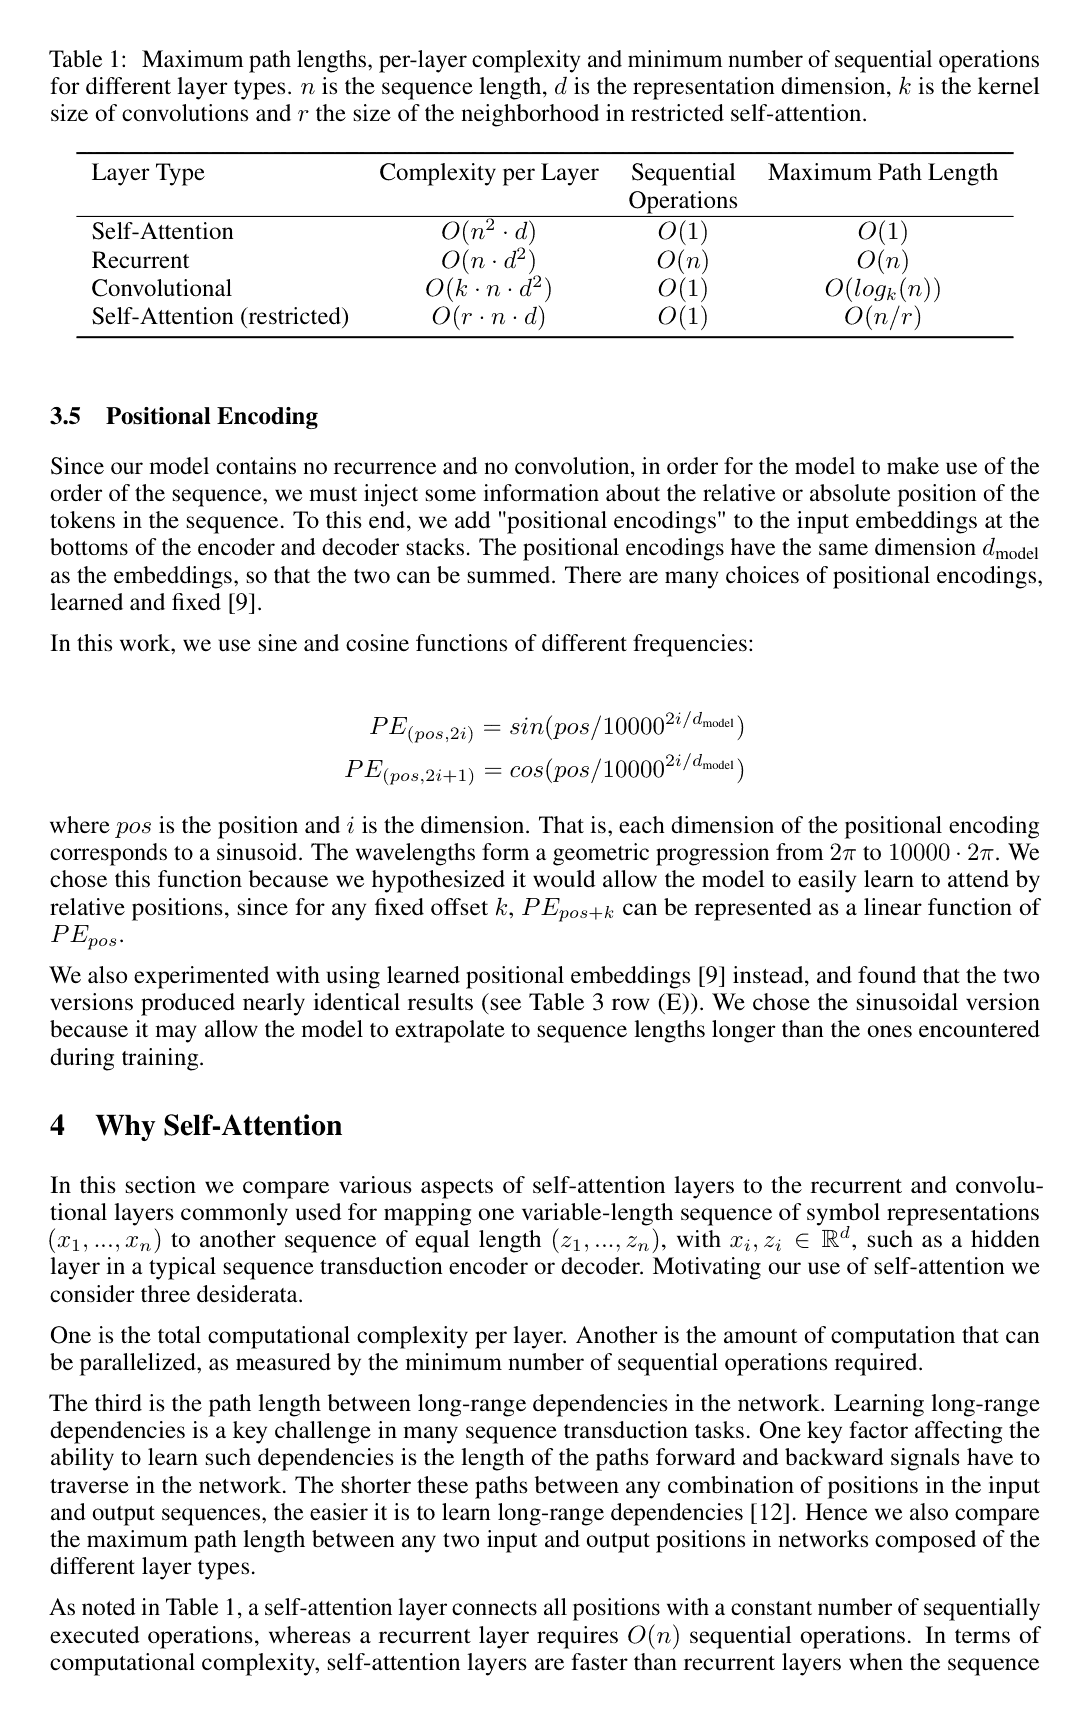
Table 1: Maximum path lengths, per-layer complexity and minimum number of sequential operations for different layer types.
表 1:不同层类型的最大路径长度、每层复杂度和最小顺序操作数。
|
Layer Type |
Complexity per Layer |
Sequential Operations |
Maximum Path Length |
|
Self-Attention |
|
|
|
|
Recurrent |
|
|
|
|
Convolutional |
|
|
|
|
Self-Attention (restricted) |
|
|
|
|
层类型 |
每层复杂度 |
顺序操作 |
最大路径长度 |
|
自注意力机制 |
|
|
|
|
循环 |
|
|
|
|
卷积 |
|
|
|
|
自注意力机制(受限) |
|
|
|
3.5 Positional Encoding
3.5 位置编码
Since our model contains no recurrence and no convolution, in order for the model to make use of the order of the sequence, we must inject some information about the relative or absolute position of the tokens in the sequence. To this end, we add "positional encodings" to the input embeddings at the bottoms of the encoder and decoder stacks. The positional encodings have the same dimension
由于我们的模型既不包含循环结构也不包含卷积结构,为了让模型能够利用序列的顺序信息,我们必须注入一些关于序列中词元相对位置或绝对位置的信息。为此,我们在编码器和解码器堆栈底部的输入嵌入中添加“位置编码”。位置编码与嵌入的维度相同,均为
In this work, we use sine and cosine functions of different frequencies:
在这项工作中,我们使用不同频率的正弦和余弦函数:
where pos is the position and
其中 pos 是位置,
We also experimented with using learned positional embeddings [9] instead, and found that the two versions produced nearly identical results (see Table 3 row (E)). We chose the sinusoidal version because it may allow the model to extrapolate to sequence lengths longer than the ones encountered during training.
我们还尝试了使用可学习的位置嵌入 [9] 进行替代,发现这两种版本产生的结果几乎相同(见表 3 行 (E))。我们选择正弦版本是因为它可能使模型能够外推到比训练期间遇到的序列更长的长度。
4 Why Self-Attention
4 为何使用自注意力机制
In this section we compare various aspects of self-attention layers to the recurrent and convolutional layers commonly used for mapping one variable-length sequence of symbol representations
在本节中,我们将自注意力层的各个方面与常用于将一个可变长度的符号表示序列
One is the total computational complexity per layer. Another is the amount of computation that can be parallelized, as measured by the minimum number of sequential operations required.
一是每层的总计算复杂度。另一个是可并行化的计算量,通过所需的最小顺序操作数来衡量。
The third is the path length between long-range dependencies in the network. Learning long-range dependencies is a key challenge in many sequence transduction tasks. One key factor affecting the ability to learn such dependencies is the length of the paths forward and backward signals have to traverse in the network. The shorter these paths between any combination of positions in the input and output sequences, the easier it is to learn long-range dependencies [12]. Hence we also compare the maximum path length between any two input and output positions in networks composed of the different layer types.
第三个是网络中长距离依赖关系之间的路径长度。学习长距离依赖关系是许多序列转换任务中的关键挑战。影响学习此类依赖关系能力的一个关键因素是前向和后向信号在网络中必须经过的路径长度。输入和输出序列中任意位置组合之间的这些路径越短,就越容易学习长距离依赖关系 [12]。因此,我们还比较了由不同层类型组成的网络中任意两个输入和输出位置之间的最大路径长度。
As noted in Table 1, a self-attention layer connects all positions with a constant number of sequentially executed operations,whereas a recurrent layer requires
如表 1 所示,自注意力层通过固定数量的顺序执行操作连接所有位置,而循环层需要
能力说明
- 逐段对齐
- 按解析出的段落翻译,每段原文都有对应的译文,标题层级与阅读顺序保持不变。
- 公式与表格保持原样
- 公式仍是 LaTeX,表格只翻译单元格里的文字,结构不变。
- 便于阅读与校对
- 原文和译文并排呈现,逐段核对译文更方便;对齐好的段落也可以直接用作双语语料。
适用场景
外文论文精读
论文逐段对照阅读,术语和公式一一对得上,适合科研与教学。
译文校对与双语语料
逐段校对机翻结果;对齐的双语段落还可以用于术语库与语料建设。
预约内测
说明你的业务场景、文档类型和预计用量,上线后优先邀请你试用。
常见问题
双语对照翻译 API什么时候上线?
正在开发中,上线后会在能力中心和控制台通知。现在可以通过页面上的“预约内测”联系我们,说明场景和预计用量,我们会优先邀请。
双语对照翻译 API上线前,先聊聊你的场景
告诉我们你的业务场景和预计用量,上线后优先邀请内测。